
Random error vs. systematic error is one of the most important distinctions in measurement theory because every score, estimate, and classification decision depends on how error enters the data. In psychometrics, measurement error is the gap between an observed score and the value a person, behavior, or attribute would have under perfectly consistent measurement conditions. That gap is never purely academic. It influences test reliability, validity, fairness, clinical thresholds, admissions decisions, workplace assessments, and scientific conclusions. If you misunderstand the type of error present, you can spend months refining the wrong part of an instrument.
In practice, I treat measurement error as a design problem before I treat it as a statistical problem. A survey item may be ambiguous, a rater may drift, a timing device may lag, or respondents may guess. Some of these influences push scores around unpredictably; others push them in a stable direction. That simple distinction separates random error from systematic error. Random error introduces noise that varies from one observation to the next. Systematic error introduces bias that consistently shifts scores upward, downward, or toward particular groups or response patterns.
Why does this matter so much in psychometrics and measurement theory? Because the two error types damage data in different ways and require different remedies. Random error usually reduces precision and lowers reliability estimates. Systematic error can leave reliability looking acceptable while undermining validity, comparability, and interpretability. A scale can produce highly consistent scores and still be wrong in a predictable way. That is exactly why reliability is necessary but never sufficient evidence for measurement quality.
Within this broader hub on measurement error, it helps to define several related terms clearly. An observed score is the score you record. A true score, in classical test theory, is the expected score over an infinite number of parallel measurements. Error variance is the portion of score variance not attributable to the construct of interest. Reliability is the proportion of observed-score variance attributable to true-score variance. Validity concerns whether score interpretations and uses are supported by evidence. Bias is systematic deviation from the intended target. Precision describes how tightly repeated observations cluster, while accuracy describes closeness to the intended value.
These definitions also explain a common confusion. People often assume accuracy and precision rise together, but they can move apart. A test form may yield stable rankings across administrations yet systematically overestimate ability for one subgroup because of construct-irrelevant language demands. Likewise, a symptom checklist may be unbiased on average but noisy within individuals because mood, fatigue, and context alter responses. Distinguishing random error vs. systematic error lets researchers diagnose whether the core problem is inconsistency, bias, or both. That diagnosis shapes item revision, rater training, calibration studies, equating, and quality control across the full assessment lifecycle.
What random error and systematic error mean in psychometrics
Random error is unpredictable fluctuation around a target value. In psychometric data, it comes from transient influences that vary across occasions, items, raters, or testing environments: distraction, guessing, temporary anxiety, keyboard slips, inconsistent lighting, or small timing differences. Because these influences are irregular, they tend to average out over repeated observations, but they still widen score distributions and weaken correlations. In classical test theory, random error is usually conceptualized as having an expected value of zero across repeated measurements, even though any single person’s observed score may be above or below the true score at a given moment.
Systematic error is consistent distortion built into the measurement process. It is not just variability; it is directional. If an item set consistently advantages respondents with specific cultural knowledge unrelated to the target construct, that is systematic error. If a rater is chronically lenient, if a scale is miscalibrated, if social desirability inflates self-reports, or if a testing platform adds latency only on older devices, scores can shift in a regular pattern. Unlike random error, systematic error does not disappear simply by averaging more observations if the bias remains embedded in every observation.
The practical distinction is direct. Random error primarily harms precision. Systematic error primarily harms accuracy and interpretive validity. Many real assessments contain both. A reading comprehension test may include noisy performance from fatigue and also a biased passage selection that disadvantages English learners independently of reading ability. When that happens, standard reliability statistics tell only part of the story. Analysts need to inspect score distributions, subgroup functioning, calibration drift, response processes, and external criteria.
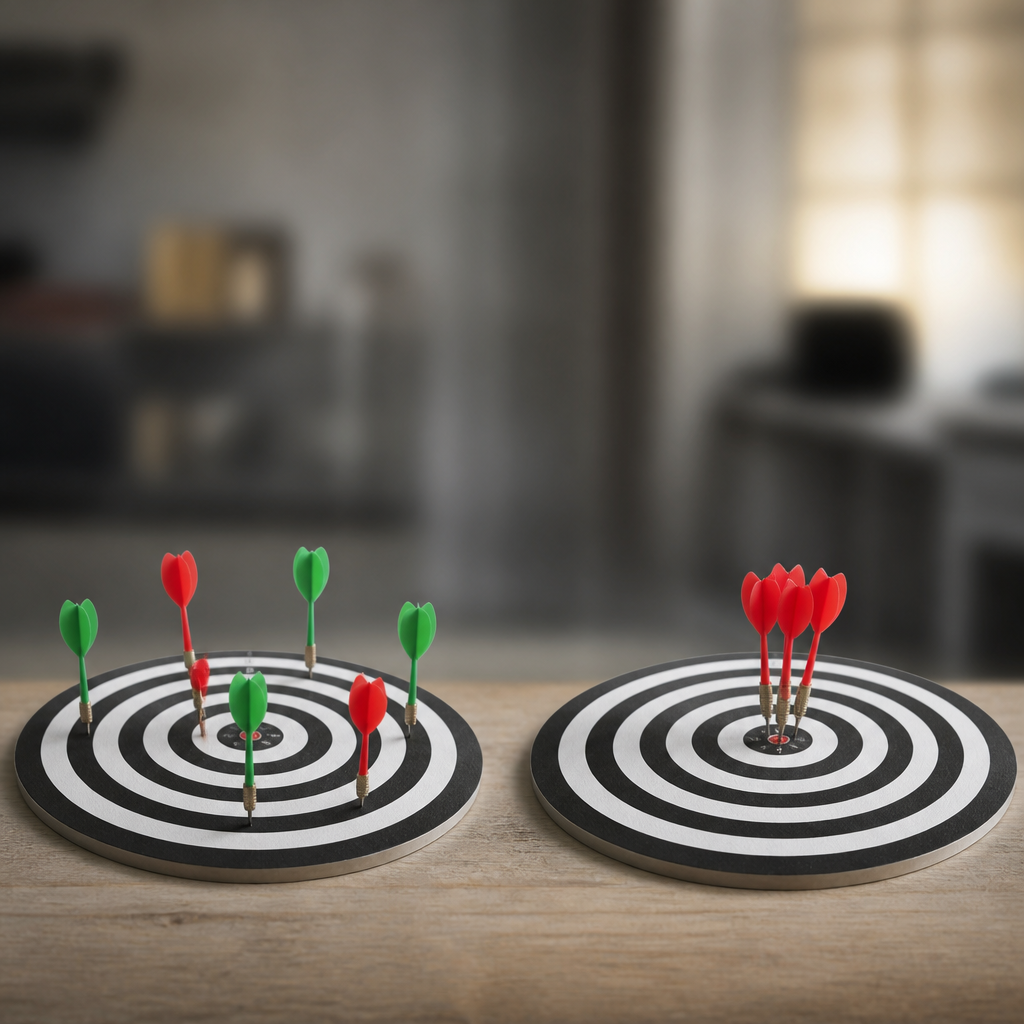
One useful way to think about the difference is with a dartboard analogy translated into assessment terms. Random error scatters darts around the board; systematic error shifts the cluster away from the bullseye. In measurement programs I have worked on, this shows up when form difficulty bounces slightly from administration to administration, which is mostly random, versus when one administration mode consistently yields lower scores because instructions are truncated on mobile screens, which is systematic. The first issue calls for more observations or better standardization. The second calls for redesign.
How measurement error appears across tests, surveys, ratings, and experiments
Measurement error is not confined to one method. In cognitive testing, random error can arise from short-term illness, distractions in remote settings, accidental omissions, or too few items sampling a broad domain. Systematic error may appear through poor test blueprints, speededness that contaminates power measurement, or differential item functioning linked to language background. In personality and attitude scales, random error often comes from inconsistent interpretation of vague items. Systematic error often comes from acquiescence, extreme responding, social desirability, or item wording that points respondents toward socially approved answers.
Observer-based measures create another pattern. In structured interviews or performance ratings, random error can result from rater fatigue, incomplete note taking, or inconsistent opportunities to observe behavior. Systematic error emerges when raters show halo effects, severity or leniency trends, central tendency bias, or stereotypes tied to demographic cues. In educational assessment, scoring rubrics can reduce random error by clarifying expectations, yet they do not automatically remove systematic error if the rubric itself rewards stylistic polish more than the target construct. That is a validity problem, not merely a reliability problem.
Experimental and clinical measurements display the same logic. A reaction-time task may show random error from trial-to-trial attentional fluctuation, but systematic error from device latency or browser differences. A depression inventory may show random noise from day-specific mood, but systematic overreporting if respondents believe elevated scores increase access to services. Even physiological indicators can carry both types: random sensor noise and systematic calibration offset. The lesson is that measurement error is method-general. Any observed score can be distorted by unstable noise, stable bias, or some combination that requires separate investigation.
| Measurement context | Common random error sources | Common systematic error sources | Typical remedy |
|---|---|---|---|
| Achievement test | Guessing, fatigue, distraction | Miskeyed items, biased content, form difficulty shift | Increase item quality, equate forms, review item fairness |
| Self-report scale | Transient mood, careless clicking | Acquiescence, social desirability, leading wording | Revise wording, add validity checks, model method effects |
| Rater score | Attention lapses, inconsistent sampling | Leniency, severity, halo, stereotype effects | Train raters, monitor drift, use many-facet models |
| Digital task | Trial variability, network lag spikes | Device latency, browser rendering differences | Standardize platform, benchmark hardware, calibrate timing |
Effects on reliability, validity, fairness, and score interpretation
Random error and systematic error affect score quality differently, and that difference sits at the center of psychometric evaluation. Random error inflates the denominator of observed variance, which usually lowers internal consistency, test-retest coefficients, and interrater agreement. The result is wider confidence intervals and less stable rank ordering. When precision drops, small score differences become hard to interpret. In high-stakes settings, that means more uncertainty around cut scores, classification consistency, and growth estimates. Standard errors of measurement exist largely to quantify the practical impact of random error on an individual score.
Systematic error is often more dangerous because it can hide behind impressive reliability. A scale with consistently biased items can produce high coefficient alpha or omega and still fail to measure the intended construct accurately. In selection contexts, this can distort decisions for entire groups. In clinical screening, it can push patients above or below intervention thresholds. In longitudinal designs, systematic changes in administration procedures can mimic real change. Researchers then mistake method artifacts for development, treatment effects, or group differences.
Fairness concerns belong here as well. Differential item functioning, measurement noninvariance, and mode effects are all mechanisms through which systematic error can become inequity. If people with the same latent trait level have different probabilities of endorsing an item because of language load, cultural familiarity, or interface design, comparisons are compromised. Random error can also have fairness implications if it disproportionately affects some groups through unstable testing conditions, but the strongest fairness threats usually involve patterned bias. That is why subgroup analyses, invariance testing, and accessibility reviews are central quality-control steps rather than optional extras.
Interpretation suffers when analysts fail to separate these error types. Suppose a school district notices score volatility across benchmark tests. If the cause is random form sampling error, adding well-targeted items and improving equating may help. If the cause is systematic curricular mismatch across schools, more items will not solve the real problem. Likewise, if an employee assessment shows high consistency but weak prediction of job performance, the likely issue is not simply noise; it may be construct underrepresentation or contamination. Good measurement practice starts by matching the observed symptom to the underlying error mechanism.
How psychometricians detect and reduce each type of error
Detecting random error starts with evidence on consistency and precision. Internal consistency indices such as coefficient alpha and omega assess how coherently items behave, though neither proves unidimensionality by itself. Test-retest reliability estimates temporal stability. Interrater reliability addresses agreement across scorers. Generalizability theory goes further by partitioning variance across facets such as items, raters, and occasions, which is especially useful when error sources are multiple. In item response theory, information functions show where along the latent trait scale measurement is most precise and where random error is larger.
Reducing random error usually means better standardization and denser sampling of the construct. Clear administration scripts, sufficient test length, high-quality items, stable testing environments, trained raters, and repeated observations all help. In practice, I have seen reliability improve more from rewriting ambiguous items than from simply adding new ones, because poor items contribute both noise and interpretive confusion. Digital platforms also need technical quality checks. Keyboard polling rates, screen refresh differences, and browser timing behavior can materially affect reaction-time precision if left unmanaged.
Detecting systematic error requires different tools. Content review by subject-matter experts addresses construct underrepresentation and irrelevant variance. Cognitive interviewing reveals how respondents interpret items and whether wording triggers unintended reasoning. Differential item functioning analysis flags items that behave differently across groups after matching on the target trait. Multi-group confirmatory factor analysis tests measurement invariance. In rater-mediated assessments, many-facet Rasch measurement can identify severity, leniency, and drift. Calibration studies, benchmark samples, and external criterion checks help uncover directional score shifts that consistency statistics alone cannot reveal.
Reducing systematic error often means redesign rather than minor adjustment. Remove biased content, align the blueprint to the construct definition, revise instructions, standardize accommodations, recalibrate devices, retrain raters against anchors, and separate target constructs from nuisance demands. Sometimes statistical correction is appropriate, such as equating forms or modeling method factors, but correction should not replace source-level repair. The cleanest solution is to prevent bias upstream. For a measurement error hub, that is the core lesson: random error asks how much noise is present, while systematic error asks whether the instrument is aiming at the right target for every intended use. Build error audits into every instrument review cycle.
Random error vs. systematic error is not a narrow technical distinction; it is the organizing framework for understanding measurement error across psychometrics and measurement theory. Random error produces instability, wider uncertainty, and weaker precision. Systematic error produces bias, distorted comparisons, and invalid inferences. Both can coexist, and both require deliberate diagnosis. Reliability evidence mainly helps with noise. Validity, fairness, invariance, calibration, and response-process evidence help uncover directional problems that reliability alone cannot detect.
The practical takeaway is simple. When scores look inconsistent, ask what is adding fluctuation. When scores look consistent but questionable, ask what is shifting them in a patterned way. Use classical test theory, generalizability theory, item response theory, rater monitoring, cognitive interviewing, and invariance testing as complementary tools rather than substitutes. The strongest measurement programs do this routinely, from blueprint design through operational monitoring.
If you manage assessments, surveys, ratings, or experiments, audit your instrument for both noise and bias before making decisions from the data. That single habit will improve score interpretation, strengthen fairness, and make every downstream analysis more credible.
Frequently Asked Questions
What is the difference between random error and systematic error?
Random error is unpredictable variation in measurement that causes observed scores to fluctuate around a person’s or object’s underlying value. It comes from inconsistent influences such as temporary distractions, fatigue, guessing, rater variability, minor environmental changes, or moment-to-moment shifts in performance. Because it is unsystematic, random error can push a score either upward or downward. Across repeated measurements, these fluctuations tend to average out, which is why random error is often associated with imprecision rather than consistent distortion.
Systematic error, by contrast, is a consistent bias built into the measurement process. It shifts scores in a particular direction or distorts them in a patterned way. In psychometrics, this might happen if a test consistently favors one group because of biased wording, if a calibration problem makes all readings too high, or if an assessment procedure consistently penalizes certain response styles. Unlike random error, systematic error does not cancel out over repeated observations. It remains embedded in the data unless the source of bias is identified and corrected.
The distinction matters because the two errors affect measurement quality differently. Random error primarily lowers reliability by making scores less stable and less repeatable. Systematic error threatens validity by making the test measure something in a biased or contaminated way. In practice, a measure can be highly reliable yet still flawed if it is consistently wrong. That is why good measurement theory always asks two questions: are the scores consistent, and are they accurate?
Why is the distinction between random and systematic error so important in psychometrics?
In psychometrics, every score is used to support some kind of interpretation or decision. That could mean diagnosing a disorder, placing a student, selecting applicants, estimating ability, tracking treatment progress, or evaluating fairness across groups. If measurement error is misunderstood, the resulting decisions can be misleading or harmful. Random error makes scores noisy, which means a person’s observed result may not reflect their standing under stable conditions. Systematic error is even more serious because it creates a repeatable distortion that can make the wrong conclusion look dependable.
This distinction sits at the center of reliability and validity. Reliability is concerned with consistency: if the same construct were measured again under similar conditions, would the score be similar? Random error reduces that consistency. Validity asks whether the score supports the intended interpretation. Systematic error undermines validity because the measure may be capturing irrelevant influences, cultural bias, response bias, poor administration practices, or flawed scaling rather than the target construct itself. A test that is stable but biased is not a sound test.
The distinction also matters for fairness and high-stakes decisions. Imagine a clinical cutoff, admissions decision, or employee screening score. Random error can place someone just above or below a threshold by chance, especially when scores are close to the decision boundary. Systematic error can make an entire subgroup appear stronger or weaker than it truly is because of biased content, differential access, translation issues, or rater expectations. For that reason, psychometric evaluation does not stop at reporting a single score. It also examines standard errors, item behavior, reliability estimates, differential functioning, and evidence about whether the test works comparably across contexts and populations.
How do random error and systematic error affect reliability and validity?
Random error is most directly tied to reliability. When random influences enter the measurement process, scores become less stable across repeated administrations, forms, raters, or items. A student who performs differently because of sleep quality, distractions, or guessing introduces variability that does not reflect true differences in the construct being measured. As that variability increases, reliability coefficients typically decrease because a smaller proportion of the observed-score variance reflects consistent differences among people. In practical terms, lower reliability means less confidence that a score would replicate under similar conditions.
Systematic error is most directly tied to validity because it introduces a pattern of bias into the measurement. If a test consistently overestimates one trait due to wording, administration conditions, cultural assumptions, or rater expectations, the resulting scores may appear consistent while still misrepresenting the construct. That is why reliability is necessary but not sufficient for validity. A broken scale that adds five pounds to every reading is highly consistent, but it is still wrong. Similarly, a psychological measure can produce stable scores and still fail to support accurate interpretations if those scores are contaminated by systematic influences.
That said, the relationship is not completely separate. Random error can also weaken validity because noisy scores make it harder to detect real relationships and can blur distinctions among individuals. Systematic error can sometimes affect apparent reliability too, especially if the bias is tied to stable subgroups or persistent method effects. The key point is that reliability concerns repeatability, while validity concerns correctness of interpretation. Strong measurement requires both: low random error so scores are dependable, and low systematic error so they are not consistently biased.
What are common sources of random and systematic error in testing and assessment?
Common sources of random error include temporary and unpredictable factors that disrupt consistency. In testing, these can include fatigue, anxiety, illness, distractions in the room, accidental marking mistakes, variable attention, guessing, day-to-day mood changes, and inconsistencies in scoring when raters are not fully aligned. Even well-designed instruments are affected by some degree of random fluctuation because human behavior and testing conditions are never perfectly stable. In observational and rating-based systems, random error can also come from brief lapses in concentration, ambiguous responses, or chance differences in how items are interpreted from one occasion to the next.
Systematic error tends to come from built-in features of the measure or administration process that create repeatable bias. Examples include poorly calibrated equipment, leading or confusing item wording, nonrepresentative item content, scoring rubrics that reward irrelevant skills, test forms that differ in difficulty, biased norms, and administration procedures that vary consistently across settings. In psychometrics, systematic error is especially concerning when it reflects construct-irrelevant variance, such as reading burden on a math test, language complexity on a clinical screening tool, or cultural assumptions that advantage some test takers and disadvantage others.
Rater effects can produce either type of error depending on the pattern. If a rater is inconsistently severe from one response to another, that creates random error. If the rater is always too harsh or too lenient, that creates systematic error. The same logic applies to technology-based assessments. Intermittent glitches may act like random noise, while a scoring algorithm trained on biased data may introduce systematic distortion at scale. Identifying the source of error is essential because the remedy depends on the type: better standardization, stronger training, improved item design, calibration checks, fairness analyses, and repeated measurement strategies all target different parts of the problem.
How can researchers and practitioners reduce random error and systematic error?
Reducing random error starts with making measurement conditions as consistent as possible. That includes standardizing instructions, controlling distractions, improving item clarity, training raters carefully, using enough high-quality items, and choosing administration procedures that minimize chance fluctuations. In many cases, repeated measurement helps because averaging across multiple items, forms, occasions, or raters reduces the impact of one-off influences. Reliability analysis, internal consistency estimates, interrater agreement, and standard error of measurement are all useful tools for detecting whether scores are too unstable for the decisions being made.
Reducing systematic error requires a different strategy because bias does not disappear through repetition alone. Researchers must examine whether the instrument is consistently mismeasuring the construct. That means evaluating content relevance, checking calibration, studying group differences carefully, testing for differential item functioning, reviewing translation quality, validating score interpretations, and ensuring that administration procedures are equivalent across contexts. In assessment settings, it is also important to separate the target construct from irrelevant demands such as language complexity, motor speed, prior familiarity with format, or culturally specific assumptions.
The strongest measurement programs treat error control as an ongoing process rather than a one-time technical check. They pilot instruments, analyze item performance, revise flawed content, monitor scoring systems, retrain raters, and revisit norms and validity evidence as populations and uses change. For practitioners, the practical lesson is simple: never treat a score as perfectly exact. Instead, interpret it in light of measurement uncertainty and possible bias. That is especially important near clinical thresholds, admissions cut scores, and other high-stakes boundaries where even small errors can change outcomes. Good measurement is not just about producing numbers; it is about producing numbers that are consistent enough to trust and accurate enough to use fairly.





